Artificial intelligence · 2025–
What is agentic AI, and how is an organization's fluency in it measured?
Agentic AI is artificial intelligence that carries out whole tasks — it uses tools, chains steps and acts on systems — instead of just conversing and returning text. FAROL, the research group Giordano Cabral founded in 2025 with Filipe Calegário and which in 2026 becomes the Instituto FAROL de Fluência Agêntica (FAROL Institute of Agentic Fluency), measures how organizations and people actually work with agentic AI (farol-ia.org). The group's thesis is that "AI maturity" is a broken concept and that what should be measured is fluency: a continuous state that is lost without practice, not a position once reached. Fluency is measured on six axes — knowledge, tools and integration, delegation and autonomy, processes, productivity and results, learning and culture — on a scale from N0 to N5, against a master bank of 264 items in four families, 15 major questions and three depths (knowing, doing, articulating).
01 · Agentic AI
What is agentic AI, and what distinguishes it from generative AI?
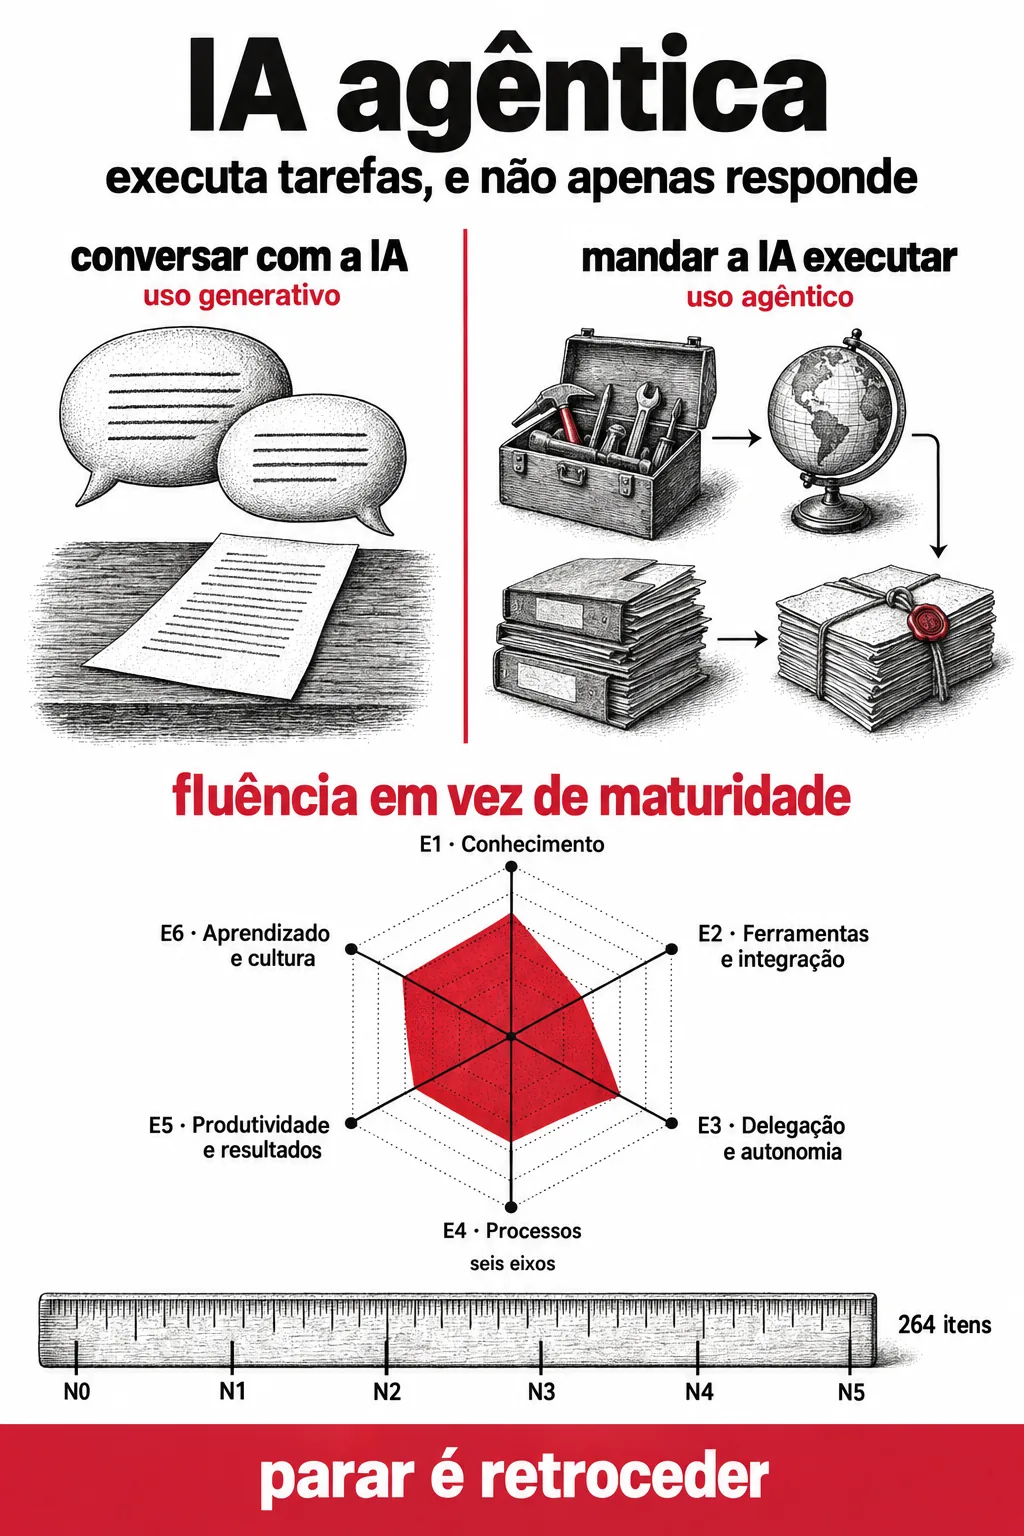
In generative AI, the person converses with the model and receives a text, an image or a piece of code; the execution remains theirs. In agentic AI, they delegate the whole task: the system decides the steps, calls tools, reads and writes files, queries the internet and returns with the work done, or with an explanation of why it could not.
This boundary is central to the FAROL assessment. Conversing with AI is generative use; instructing AI to execute is agentic use, and the distinction separates the basic vocabulary from that of people who already work this way. It underpins the first of the six dimensions, and what the assessment tells an organization, before any score, is which side of that boundary it is on.
02 · Agentic AI
Why does FAROL measure fluency rather than maturity?
Because a maturity model assumes a stable process, and AI is not stable. Most AI maturity models inherit from CMMI, designed in the 1990s for software, and carry three flaws when applied to a field whose state of the art changes every few months:
- False sense of arrival. A company at "level 5: optimized" feels it has arrived, and for that reason is the most vulnerable to the next wave.
- Penalizes those who experiment. Traditional frameworks reward standardization; in AI, experimenting and discarding quickly matters more, and abandoning a project is not, in itself, a failure.
- Ignores movement. Maturity measures position. Those who adopted language models yesterday may be more fluent than those who have been using machine learning for five years.
The alternative is fluency, by analogy with a language: continuous, because stopping means falling behind; distributed, because an organization can be strong in data and weak in people; and dependent on the surrounding ecosystem.
What evidence supports the choice to measure fluency?
Three findings from outside the group:
- Adoption is no longer a distinguishing factor. The 2025 Stack Overflow survey reports 84% AI use among developers, with trust falling from 40% to 29% in one year and 66% reporting solutions that are "almost right, but not quite".
- Perception is misleading. METR's July 2025 controlled trial found that experienced developers working on mature projects were 19% slower with AI, while believing they were 20% faster.
- The Brazilian gap is one of fluency. The presence of tools is massive; what is missing is maturity in delegation, a cultural and organizational matter.
03 · Agentic AI
What are the six dimensions of agentic fluency?
FAROL measures each dimension separately, because an average hides precisely the imbalance that matters.
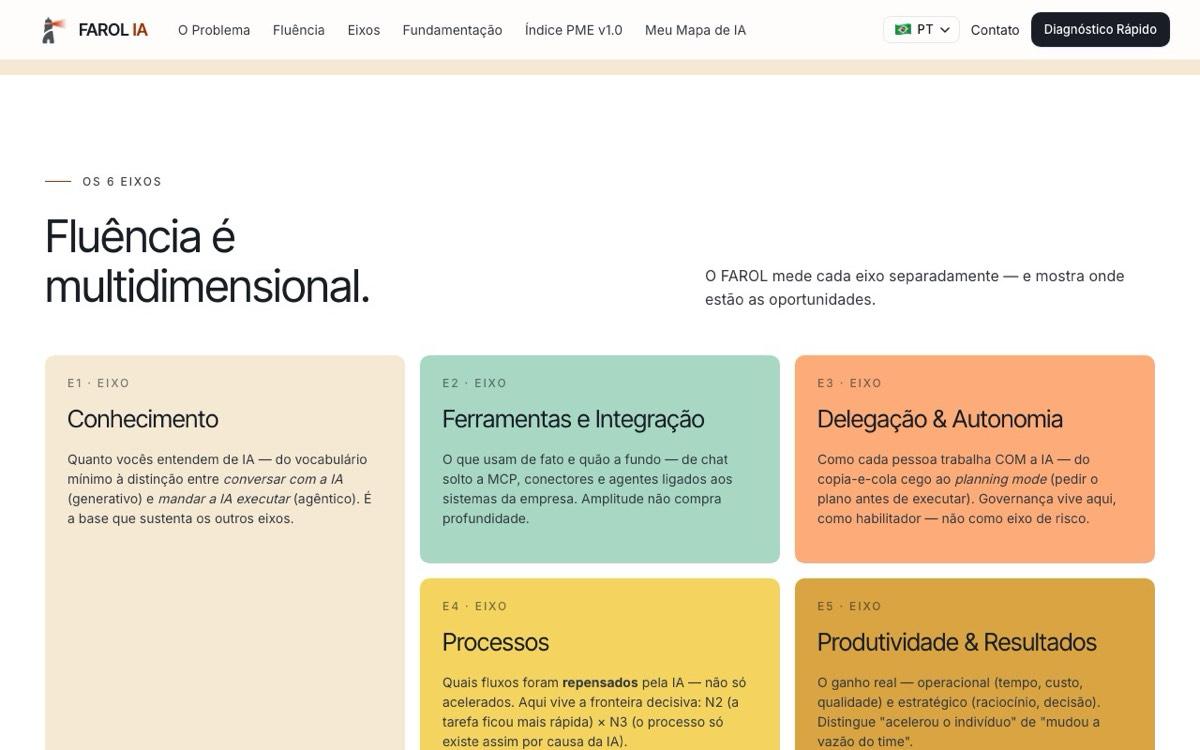
- E1 · Knowledge — how much one understands about AI, from basic vocabulary to the distinction between talking to AI and instructing AI to execute. It is the foundation for the other dimensions.
- E2 · Tools and integration — what is actually used and in what depth, from standalone chat to MCP, connectors, and agents linked to company systems. Breadth does not buy depth.
- E3 · Delegation and autonomy — how each person works with AI, from blind copying and pasting to planning mode, in which a plan is requested before execution. Governance belongs here, as an enabler.
- E4 · Processes — which workflows have been rethought through AI, rather than simply accelerated. The defining question: did the task become faster, or does the process only exist in this form because of AI?
- E5 · Productivity and results — operational gains (time, cost, quality) and strategic gains (reasoning, decision-making). Distinguishes "made the individual faster" from "changed the team's throughput."
- E6 · Learning and culture — how the organization stays up to date. This is the driving force: without it, any level achieved regresses.
The scale runs from N0 to N5 in version 3, the canonical one, and ran from A to E in version 1. The stated basis is a critical synthesis of 928 formulations of AI fluency and maturity published by consultancies, universities and big tech companies (among them MIT CISR, Gartner, Deloitte, Cisco, Forrester/IBM, Microsoft, Salesforce and NIST), recalibrated for the Brazilian context.
04 · Agentic AI
How is the instrument constructed?
The instrument has a tree structure. Since each respondent uses one stack of tools, not all of them, the questionnaire first identifies the stack and then opens questions within it.
Data collection has five stages, organized by cost: level 1, one response per organization, ten to fifteen minutes, free of charge; level 2, one response per person, around five minutes, free of charge; level 3, structured interviews, around one hour per person; levels 4 and 5, assisted exploration in greater depth and on-site work.
The quality of AI output and the content of conversations are excluded from measurement; conversation content never leaves the respondent's computer. What the index does not measure is covered under fluency.
What objections does the group itself publish?
Two, published alongside it: Goodhart's law (an indicator that becomes a target ceases to measure what it represents) and the fact that a measure that has been announced is a promise that can be called in later. Both are developed in fluency.
05 · Agentic AI
Which agentic fluency instruments are open to the public?
Six are available online, with no prior registration and free of charge:
- AI Index for companies — a leader answers on behalf of the organization and leaves with the radar of the six axes and the next leap. Three to eight minutes, immediate result.
- Meu Mapa de IA — a research instrument in game form for students, taking about fourteen minutes on a mobile phone, with an on-screen consent form.
- AI adoption observatory — the aggregated dashboard of Meu Mapa de IA: 2,943 responses in the 09/14/2026 snapshot, with suppression of every cell below five. Exportable as CSV.
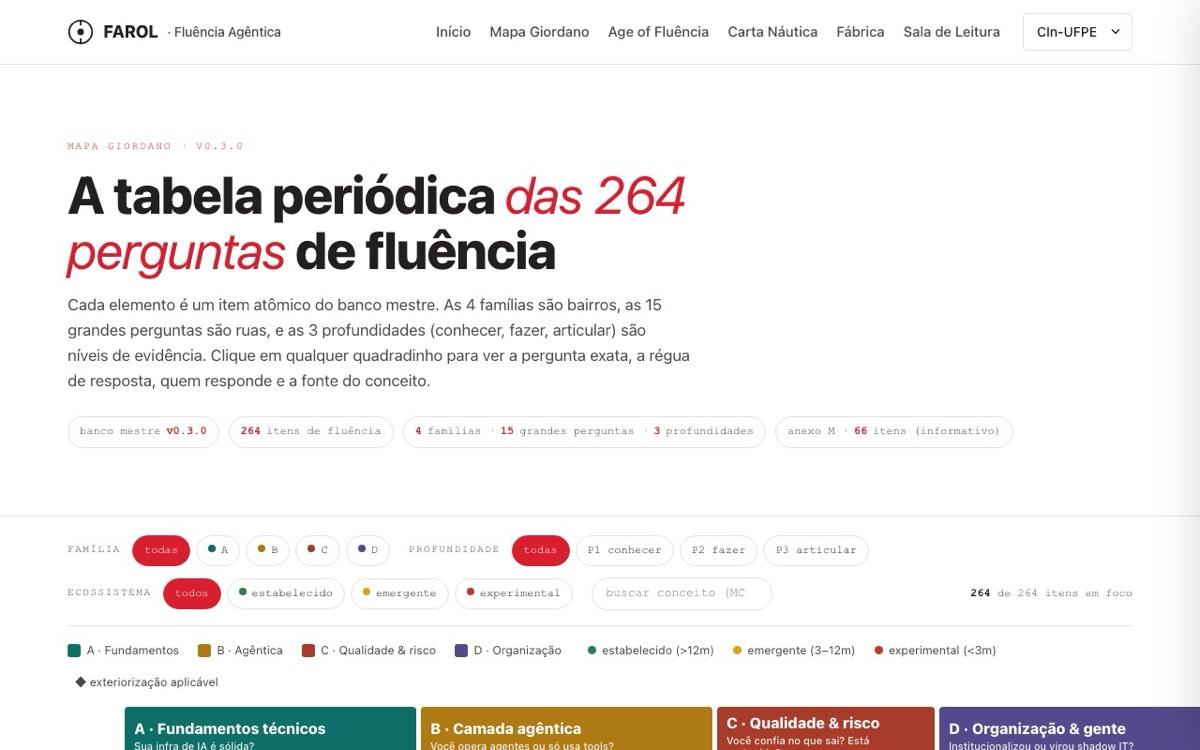
- Mapa da Fluência Agêntica — five visual interpretations of the same database of 264 items: a periodic table, maturity eras, a nautical chart, a factory, and a reading room.
- FAROL Software — the software engineering vertical: 37 mapping questions and 77 optional questions about practices, taking fifteen to sixty minutes.
- Prototype laboratory — six ways to complete the diagnostic without the feel of a form, open to anyone who wants to comment on the design.
06 · Agentic AI
What did Bolão das IAs measure about model behavior?
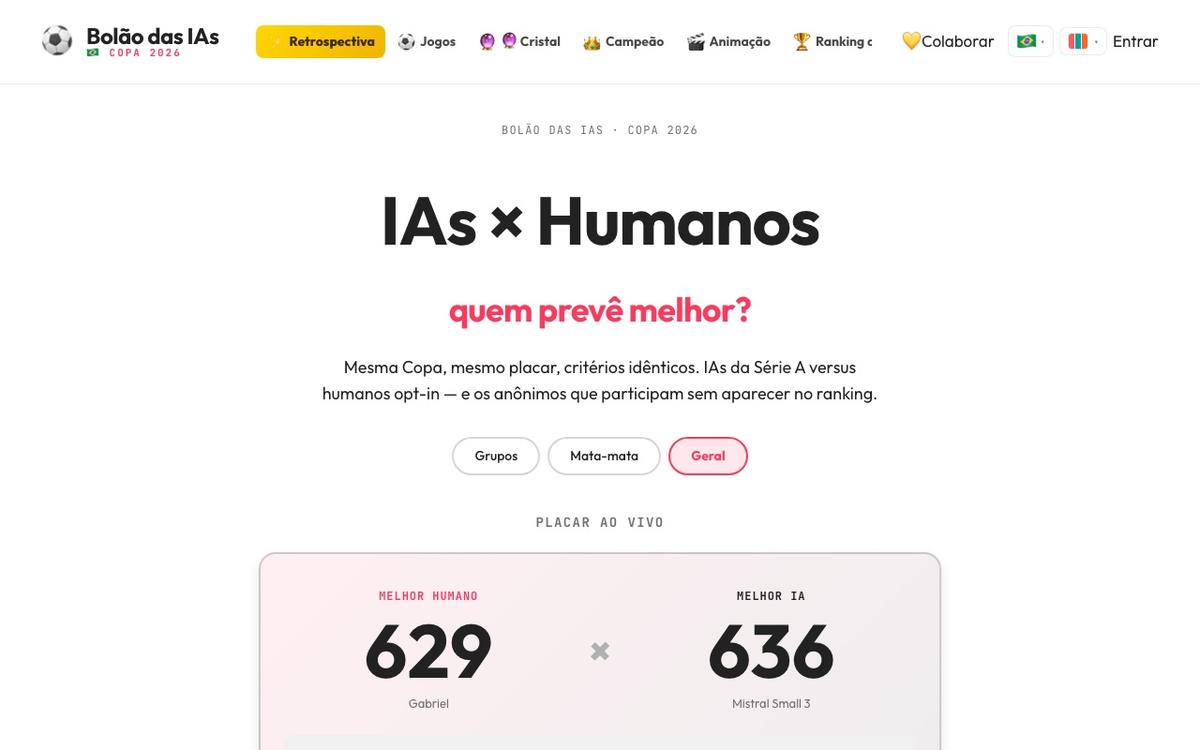
O Bolão das IAs · Copa do Mundo 2026 was the first experiment by Arena das IAs, the group's public experiments initiative: 124 models predicted the outcomes of all 104 World Cup matches under the same prediction pool rules, competing in the same ranking as humans. There were 5,797 predictions over 38 days, from June 11 to July 19, 2026, with everything recorded at bolao.arenadasias.com.br and in the GitHub repository.
Eleven interface models, the "Series A", made predictions like people: they opened the browser and researched news, injuries and form before locking in the score. The rest ran through an API, with the same prompt.
Winners among the AIs, tied at 636 points: Mistral Small 3, with 22 exact scores, and Grok 4 Fast Reasoning, with 20. Série A winner: ChatGPT 5 Thinking, with 616. The top human scored 629 points, ahead of 121 of the 124 AIs.
The consensus among the 124 pointed to Brazil as champion, and the team was eliminated in the round of 16. In the semifinal France 0 × 2 Spain, none of the 62 AIs consulted predicted the Spanish victory. In the third-place match, France 4 × 6 England, none of the 63 got the score right, and only five even bet on an English win. Twelve models reached twenty or more exact scores, across 104 matches. The whole experiment is in the essay.
The CIn-UFPE portal covered the experiment at its launch on June 11, 2026, and at its conclusion on July 22, 2026.
07 · Agentic AI
How long has Giordano Cabral been working with agents?
Giordano Cabral has worked with intelligent agents since his undergraduate studies, at CIn/UFPE.
- 1999–2001 — real-time music and audio generation: the project "Agentes Inteligentes para Ambientes Complexos: Estudo do Acompanhamento Musical em Tempo Real" (Intelligent Agents for Complex Environments: A Study of Real-Time Musical Accompaniment), with Hugo Santana and Geber Ramalho.
- 2003–2008 — doctorate in generative artificial intelligence, with Jean-Pierre Briot and François Pachet, at LIP6 of the Sorbonne / Université Pierre et Marie Curie (Paris 6), with four years of collaboration with the SONY Computer Science Laboratory. The thesis Harmonisation automatique en temps réel was defended on 07/09/2008, with the mention très honorable (theses.fr/2008PA066236).
- 2020–2024 — PRAIA, Centro de Pesquisa Realmente Aplicada em Inteligência Artificial (Center for Truly Applied Research in Artificial Intelligence), with Geber Ramalho; and, in 2024, three texts with Jean-Pierre Briot and Fabio Cozman on strategies, challenges, and opportunities for AI in Brazil, deposited in HAL (hal.science/hal-04663796).
- 2023 — text on machine autonomy: Will AI's Next Wave of Super Intelligence Replace Human Ingenuity? It's Complicated, published in Grit Daily on 12/15/2023 and updated on 05/10/2024. The thesis is that an artificial general intelligence that surpasses humans in nearly everything is unlikely, and that the more interesting bet is not to make the machine surpass humans at what humans already do, but to use it for what humans cannot do, such as non-human observations and the processing of dimensions beyond perception.
- 2025–2026 — FAROL, which measures the use of agentic AI in the work of organizations and people.
08 · Agentic AI
Where does agentic AI fit into Giordano Cabral's teaching?
In the course Tendências em Mídia e Interação (Trends in Media and Interaction) (CIN0055), in 2026.2, five of the nineteen topics raised by the class concern agentic AI: agentic programming and the developer as orchestrator; containment, security and identity of autonomous agents; the trust infrastructure (memory, observability and evaluation); the agentic internet, when the user is a machine; and agents with a wallet, in machine-to-machine commerce. The topics were not chosen by the professor: they came from a catalog of 5,776 tools gathered by the class and 659 choices recorded in the system.
The course website is www.cin.ufpe.br/tmi/26-2/.
Frequently asked questions
What is agentic AI?
Agentic AI is artificial intelligence that carries out entire tasks instead of merely answering: it decides the steps, uses tools, reads and writes in systems, and returns the finished work. The practical distinction, used by FAROL (CIn/UFPE), is between talking to the AI, which is generative use, and telling the AI to execute, which is agentic use.
What is agentic fluency?
Agentic fluency is the ability of a person or organization to work with agentic AI, measured as movement rather than position. The analogy is that of a language: it is a continuous state, lost without practice, unevenly distributed within the same organization, and dependent on the surrounding ecosystem. The concept was formulated in 2025 by FAROL, founded by Giordano Cabral at CIn/UFPE, as an alternative to AI maturity models.
How does FAROL measure an organization's fluency?
Across six axes (knowledge; tools and integration; delegation and autonomy; processes; productivity and results; learning and culture), on a scale from N0 to N5, against a master bank of 264 items organized into four families, 15 major questions, and three depths (knowing, doing, articulating). Data collection has five levels of depth, from a self-administered diagnostic of ten to fifteen minutes to in-person work. The entry diagnostic, the AI Index for companies, is free, takes three to eight minutes, and returns the result immediately, with no prior registration.
Why AI "fluency" rather than "maturity"?
Because maturity models inherit from CMMI, designed in the 1990s for stable software, and AI is not stable. According to FAROL's formulation, this produces three flaws: it gives a false sense of arrival to those who reach the top of the scale, it penalizes those who experiment and discard quickly, and it measures position instead of speed of adaptation, which is what matters in a field whose state of the art changes every few months.
Who founded FAROL, and where is it based?
FAROL was founded in 2025 by Giordano Cabral, with Filipe Calegário, as a research group of the Centro de Informática of the Universidade Federal de Pernambuco, in Recife; in 2026 it becomes the Instituto FAROL de Fluência Agêntica (FAROL Institute of Agentic Fluency). The institutional contact is farol@cin.ufpe.br and the address is farol-ia.org, published in nine languages. The name comes from what the group does: FA for agentic fluency (fluência agêntica), and ROL for the three movements that operationalize it: Radar, the continuous sweep of what emerges; Observatório (Observatory), where the organization stands in the race; and Laboratório (Laboratory), experimentation.
Are AIs better than humans at prediction?
In the public experiment conducted by the group, not in the cases that determine outcomes. In Bolão das IAs da Copa de 2026, with 124 models, 104 matches and 5,797 predictions between June 11 and July 19, 2026, the top human scored 629 points and finished ahead of 121 of the 124 AIs. The consensus among the 124 picked Brazil as champion, and Brazil was eliminated in the round of 16; in the France 0 × 2 Spain semifinal, none of the 62 AIs consulted predicted a Spanish victory. The group's interpretation is that the models perform well in aggregate and poorly on rare events.